 NeuroDynamic
The steps
Prepare Docker on the Ubuntu computer
Run the Linux commands in an Ubuntu terminal. If Docker Engine already works, keep your installation and continue to Step 2. On a new machine, follow Docker’s official Ubuntu installation instructions: add its signing key and apt repository, install the Engine packages, then run its hello-world check. The site’s Docker guide explains the steps in more detail.
Do not paste a second installation recipe over an existing Docker setup. The official instructions explain conflicting packages and upgrades. Once installed, check both the client and server versions:
(
set -eu
sudo docker version
sudo apt update
sudo apt install -y curl openssl
)
Using sudo avoids adding your account to Docker’s administrator-equivalent group. If Docker reports a connection error, finish its installation checks before continuing.
Create the private key on Ubuntu
Ubuntu terminal. Copy this whole block once, including its brackets. It creates ~/murmur-whisper and a private whisper.env file. If that path already exists, it stops and keeps the existing key. The brackets keep a failed command from closing your terminal. If setup stops part-way, inspect the folder before trying again; do not delete an existing working configuration.
(
set -eu
umask 077
target="$HOME/murmur-whisper"
if [ -e "$target" ] || [ -L "$target" ]; then
  printf '%s\n' 'STOP: ~/murmur-whisper already exists. Inspect it; keep your existing key.' >&2
  exit 1
fi
WHISPER_KEY=$(openssl rand -hex 32)
test "${#WHISPER_KEY}" -eq 64
printf '%s\n' "$WHISPER_KEY" | LC_ALL=C grep -Eq '^[0-9a-f]{64}$'
mkdir -m 700 "$target"
cd "$target"
set -C
printf 'WHISPER_API_KEY=%s\n' "$WHISPER_KEY" > whisper.env
cat >> whisper.env <<'EOF'
WHISPER_MODEL=small
WHISPER_DEVICE=cpu
WHISPER_COMPUTE_TYPE=int8
WHISPER_THREADS=2
WHISPER_MAX_UPLOAD_MB=25
WHISPER_DISABLE_USAGE_COUNTS=1
EOF
chmod 600 whisper.env
printf '%s\n' 'Created private configuration. The API key has not been printed.'
)
The pinned configuration reference documents these settings. small chooses the speech model; CPU int8 and two threads are a conservative starting point. The file limits each upload to 25 MiB and disables optional anonymous aggregate usage counts.
Keep the file private and backed up securely. Anyone who can administer Docker can inspect container settings, including the key. Do not put this file in a shared folder or source repository.
Download and start the server on Ubuntu
Ubuntu terminal. First download the CPU image and save the immutable digest that identifies this particular download. This block stops if an image reference already exists, so a repeat does not silently replace your saved version.
(
set -eu
cd "$HOME/murmur-whisper"
test -f whisper.env
test -r whisper.env
WHISPER_KEY=$(sed -n 's/^WHISPER_API_KEY=//p' whisper.env)
test "${#WHISPER_KEY}" -eq 64
printf '%s\n' "$WHISPER_KEY" | LC_ALL=C grep -Eq '^[0-9a-f]{64}$'
if [ -e image-reference.txt ] || [ -L image-reference.txt ]; then
  printf '%s\n' 'STOP: image-reference.txt already exists. Use the saved version below, or follow the update section.' >&2
  exit 1
fi
sudo docker pull hwdsl2/whisper-server:latest
WHISPER_IMAGE=$(sudo docker image inspect --format '{{index .RepoDigests 0}}' hwdsl2/whisper-server:latest)
test "${#WHISPER_IMAGE}" -eq 93
printf '%s\n' "$WHISPER_IMAGE" | LC_ALL=C grep -Eq '^hwdsl2/whisper-server@sha256:[0-9a-f]{64}$'
set -C
printf '%s\n' "$WHISPER_IMAGE" > image-reference.txt
printf '%s\n' 'Image downloaded and its exact reference saved.'
)
Now start the saved version. This is also the block to reuse after deliberately removing a stopped container to change its configuration. It reads the private file directly; you do not need to paste your key into a command.
(
set -eu
cd "$HOME/murmur-whisper"
test -f whisper.env
test -r whisper.env
WHISPER_KEY=$(sed -n 's/^WHISPER_API_KEY=//p' whisper.env)
test "${#WHISPER_KEY}" -eq 64
printf '%s\n' "$WHISPER_KEY" | LC_ALL=C grep -Eq '^[0-9a-f]{64}$'
test -r image-reference.txt
WHISPER_IMAGE=$(cat image-reference.txt)
test "${#WHISPER_IMAGE}" -eq 93
printf '%s\n' "$WHISPER_IMAGE" | LC_ALL=C grep -Eq '^hwdsl2/whisper-server@sha256:[0-9a-f]{64}$'
sudo docker run -d --name murmur-whisper \
  --restart unless-stopped \
  --env-file "$PWD/whisper.env" \
  -v murmur-whisper-models:/var/lib/whisper \
  -p 127.0.0.1:9000:9000 \
  "$WHISPER_IMAGE"
sudo docker logs --tail 40 murmur-whisper
)
The first start includes a separate model download. A downloaded Docker image is not yet a ready recogniser. The server loads small at startup, using internet access and disk space; wait for the model-ready message. To look again, run sudo docker logs --tail 40 murmur-whisper in Ubuntu. The named model volume keeps the cache between container replacements. A different model may need another download. unless-stopped brings the container back after a reboot unless you deliberately stopped it.
Keep the port binding as shown. It restricts the speech API to the Ubuntu computer’s loopback address. Do not change it to -p 9000:9000 or forward port 9000 on your router. Docker documents both port publishing and the localhost limitations of older Engine versions; use a maintained Engine. A firewall setting alone may not control a Docker-published port as you expect.
Prove transcription works on Ubuntu
Put a few seconds of clear, non-sensitive speech in ~/murmur-whisper/test-dictation.wav on Ubuntu. A recording that exists only on Windows must be copied first.
Windows PowerShell: use an existing genuine short WAV recording in Downloads, or replace the source path with its actual location. Do not rename another audio format to .wav. Replace YOUR_USER and YOUR_SERVER with the same SSH user and server from the prerequisite, then run scp "$env:USERPROFILE\Downloads\test-dictation.wav" YOUR_USER@YOUR_SERVER:murmur-whisper/test-dictation.wav. scp copies files over SSH. Wait for a successful copy, then return to the Ubuntu terminal and ask the running server for its model list:
(
set -eu
cd "$HOME/murmur-whisper"
test -f whisper.env
test -r whisper.env
WHISPER_KEY=$(sed -n 's/^WHISPER_API_KEY=//p' whisper.env)
test "${#WHISPER_KEY}" -eq 64
printf '%s\n' "$WHISPER_KEY" | LC_ALL=C grep -Eq '^[0-9a-f]{64}$'
curl --fail-with-body -sS http://127.0.0.1:9000/v1/models \
  -H "Authorization: Bearer $WHISPER_KEY"
)
You should receive JSON containing a data list of model IDs. If this fails, fix it before connecting LexVoca. Then send the recording:
(
set -eu
cd "$HOME/murmur-whisper"
test -f whisper.env
test -r whisper.env
WHISPER_KEY=$(sed -n 's/^WHISPER_API_KEY=//p' whisper.env)
test "${#WHISPER_KEY}" -eq 64
printf '%s\n' "$WHISPER_KEY" | LC_ALL=C grep -Eq '^[0-9a-f]{64}$'
test -r test-dictation.wav
curl --fail-with-body -sS http://127.0.0.1:9000/v1/audio/transcriptions \
  -H "Authorization: Bearer $WHISPER_KEY" \
  -F file=@test-dictation.wav \
  -F model=whisper-1 \
  -F response_format=json
)
The response should be a JSON object with a text field containing your words. It need not match perfectly: check names, numbers and missing negatives. The whisper-1 request name is accepted by this image; its configured WHISPER_MODEL determines the model that actually runs. Changing that request name does not download or select a different model.
This path sends a completed recording and waits for its text. It does not show live words as you speak. A short clip can take longer than the clip itself on a CPU. For a later hardware project, see the GPU guide and its compatibility notes.
Connect from Windows and try LexVoca
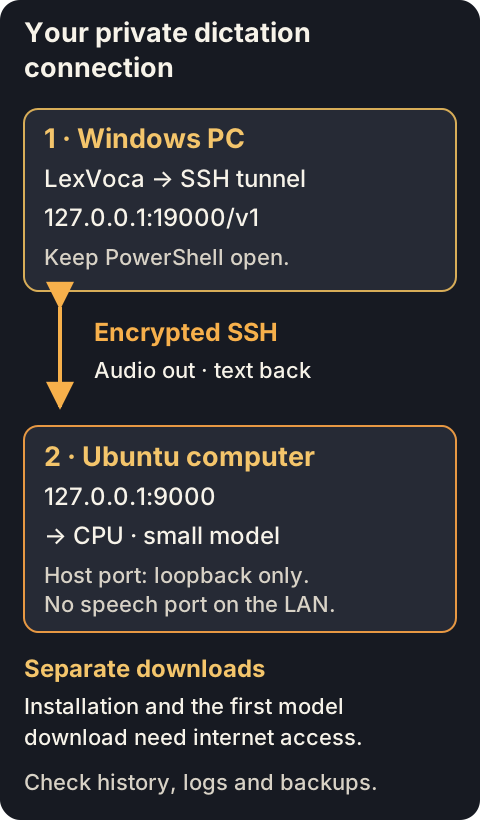
Keep the speech service bound to loopback and carry the connection over SSH. In Windows PowerShell, replace YOUR_USER and YOUR_SERVER with the Ubuntu account and the private address or hostname you already use for SSH:
ssh -N -o ExitOnForwardFailure=yes -L 127.0.0.1:19000:127.0.0.1:9000 YOUR_USER@YOUR_SERVER
Check the server’s host-key fingerprint through a trusted route on first connection. Sign in normally. The terminal may then stay blank: leave it open while you use LexVoca. It forwards Windows port 19000 through the encrypted connection to Ubuntu port 9000. Closing it or pressing Ctrl+C ends the tunnel, not the speech server. No speech port needs to be open to your LAN or the internet. The OpenSSH manual explains local forwarding.
- Open LexVoca’s settings. Under Connection → Process speech with, choose My own server. Other versions may call this “Your own server” or place it under Speech.
- In Speech server, set the base URL to http://127.0.0.1:19000/v1. Include /v1, but not /audio/transcriptions; LexVoca appends that part itself. Here, 127.0.0.1 means the Windows end of your tunnel.
- Enter the key from whisper.env in the speech API-key field, without the WHISPER_API_KEY= prefix. Read it privately on the Ubuntu computer. Do not use a LexVoca hosted-service key.
- Set the speech model to whisper-1, or use Refresh and select the model offered by this server. Leave Language blank for automatic detection, or use a language code such as en.
- Turn off Clean up transcripts with an LLM for this setup. Do not point the AI cleanup URL at the Whisper server: it is not a chat or correction model. A separate AI correction guide is coming soon.
- Save the settings, use Test connection, then Start speech test. Dictate a short, non-sensitive sentence into a blank document and check the returned text.
What makes this compatible? LexVoca’s own-server path reads /v1/models, sends a bearer-authenticated multipart file to /v1/audio/transcriptions, requests JSON and reads its text field. The reviewed server implements that contract. Some extra recognition controls sent by LexVoca are not applied by this server, so compatibility does not mean identical behaviour to the hosted service. A model-list check alone does not prove microphone capture or dictation quality.
Only the speech step is covered here. Audio goes to the server you selected; LexVoca may retain local history or failed recordings according to its settings. Review those settings and the server’s storage and logs before using sensitive material.
What stays private, and what still needs care
The intended speech path is Windows → encrypted SSH tunnel → your Ubuntu CPU → text back to Windows. The HTTP endpoints are loopback addresses on each computer; SSH encrypts the part crossing the network. This guide does not expose the speech API on a public address.
Installation and model downloads contact external providers. Aggregate server usage counts are disabled here, but that is not a complete privacy audit. LexVoca history, failed recordings, server temporary files, logs and backups need their own retention review. A rented Ubuntu server is still a computer operated by its provider. Confirm settings before sending sensitive speech.
There is no separate per-minute hosted transcription service in this path. You pay your own hardware or hosting, electricity, storage and network costs, plus any applicable LexVoca licensing. CPU speed varies; a completed recording may take longer to process than it took to speak. AI cleanup remains off, and transcription still needs checking.
Stop, restart or update
To pause the service without deleting the model cache:
sudo docker stop murmur-whisper
To use it again:
sudo docker start murmur-whisper
To change configuration, stop the container, edit whisper.env, then remove only the stopped container with sudo docker rm murmur-whisper. Repeat the docker run command from Step 3 using your saved image reference. The named model volume remains.
For an update, finish any recording and keep a secure backup of whisper.env. Preserve image-reference.txt as previous-image-reference.txt without overwriting an earlier backup. Read upstream change notes. Only then move the current reference out of the way and repeat the download block in Step 3 to save a new digest. Stop and remove only your old murmur-whisper container, then use Step 3’s start block. Repeat the model-list, audio and LexVoca checks. Retain the old local image and its digest: to roll back, stop/remove the replacement, restore the previous reference as image-reference.txt, and reuse the start block. Do not delete the model volume during either operation.
To retire this practice setup, stop and remove its container. The murmur-whisper-models volume and private configuration folder remain deliberately. Delete them only after checking that you no longer need the models or key; Docker itself can stay installed for other uses.
For everyday app controls, return to LexVoca’s Speech help.
Related reading
Sources and confidence
Reviewed 23 October 2026: upstream README and configuration, container build and API implementation, commit dated 21 October 2026. They support the image name, WHISPER settings, model cache and API contract used here. Source review and safe shell checks do not prove a live Docker installation, network isolation or recognition quality. LexVoca 2.31.6 labels reflect the earlier source check, not a fresh app walkthrough.
Something went wrong?
Cannot connect to the Docker daemon
Docker cannot connect: check sudo systemctl status docker and that you used sudo. Complete Docker’s installation checks first.
“already exists” or a copy block stops early
Do not remove a working folder or regenerate its key. Step 2 deliberately refuses an existing path; Step 3 refuses an existing image reference. For later steps, confirm you are using the same Ubuntu account, that ~/murmur-whisper contains readable whisper.env and image-reference.txt, and that the saved key is one 64-character hexadecimal value. A missing file or malformed value stops the block before a request. If setup is incomplete, inspect it before deciding what to repair; do not paste commands into another directory.
Container name “murmur-whisper” is already in use
The container name is already in use: inspect sudo docker ps -a. If this is your existing setup, start it with sudo docker start murmur-whisper; do not delete an unfamiliar container.
Connection refused or SSH “address already in use”
Connection refused: check sudo docker ps and the container logs. First get the Ubuntu curl check working, then check the SSH tunnel. A Windows “address already in use” error means port 19000 is occupied; choose another unused local port and use that same port in LexVoca.
401 / unauthorised
401 / unauthorised: the key is missing or different. Read the key from your private file and update LexVoca’s own-server profile. Changing the file alone does not change an existing container; recreate it as described below.
404 / not found
404 / not found: check the base URL ends with exactly one /v1. A different Whisper implementation may expose another API.
Long wait, model download or timeout
A long wait or timeout: check download progress, free memory, CPU use and clip length. Start with a few seconds of audio. For a smaller model, change WHISPER_MODEL to base, then recreate the container; accuracy may change. On Ubuntu, inspect sudo docker logs --tail 40 murmur-whisper for a failed download or memory error. Do not repeatedly restart a download that is progressing.
413 / upload too large
413 / upload too large: this configuration limits a file to 25 MB. Use a shorter recording for the initial check.
Empty or inaccurate text
Empty or inaccurate text: listen to the original recording, check the microphone and language setting, and try a quiet room. Do not treat uncertain text as a reliable command or instruction.
Speech works but AI cleanup fails
Speech works but cleanup fails: keep LLM cleanup off. This server provides transcription, not AI correction.